Socotra is a cloud-native, API-first core insurance platform that lets carriers, managing general agents (MGAs) and programme teams configure products, administer policies, handle billing and process claims without the release cycles that older core systems imposed. What often surprises teams after a Socotra implementation goes live is that the speed gained in product configuration does not automatically translate into speed in document production — policy packets, declarations, endorsement notices, claim letters and regulatory notices still have to be assembled, approved, delivered, archived and proven. When that work stays dependent on developers, consultants or manual assembly, the agility you bought in the core quietly leaks away at the last mile.
TL;DR
- Socotra owns the authoritative policy, billing and claims state. A document layer owns template design, assembly logic, approvals, delivery, evidence and archive metadata — the boundary between the two is the single most important architectural decision you will make.
- Document complexity in insurance rarely comes from the words. It comes from jurisdiction variation across states, provinces and regions, form editions and effective dates, nested and calculated data, multi-system sourcing, and peak-volume events such as renewals and catastrophe communications.
- An API-led integration pattern suits an API-first core well: Socotra events trigger governed generation, the document layer retrieves data, applies rules, assembles, routes for approval or signature, delivers, archives and writes a reference back.
- Experlogix Document Automation is one way insurers add that layer alongside an existing core, using a Microsoft Word-based Template Builder, Smart Forms for data capture, Smart Flows for workflow, Content Manager for versioned assets, and a documented API with role-based API keys.
- AI can accelerate configuration and initiate document workflows through governed interfaces, but regulated judgement on coverage, pricing, eligibility and claim outcomes must remain with authorised people and systems.
Happy shiny people. Insurance marketing loves the image of policyholders living their best lives, blissfully unbothered by the catastrophes their cover protects them from; a centralised document layer that lets business users manage document automation accurately and quickly, without heavy ongoing IT labour, is how the insurance professionals behind the scenes get to live their best lives too.
Where Socotra Fits in the Insurance Technology Stack
Readers who already run Socotra know the pitch: a modern core built around configurable product definitions and open APIs, so that a new product, coverage or rating change is a configuration exercise rather than a multi-quarter development project. It administers the transactional truth of the business — the policy term, the insured objects, the coverages and limits, the premium and billing position, the claim and its financials.
That role matters for document strategy because it defines what the core should be trusted for. Socotra is the system of record for policy, billing and claims state. It is the authoritative source for what was bound, when it was effective, what changed at endorsement and what a claim currently reflects. Any document layer you place around it must defer to that truth rather than recreate it.
What a core system does not naturally own is the full editorial and operational life of a document: who approved the wording, which clause edition applied on a given effective date, which brand or programme variant was used, which channel the document went out on, whether delivery succeeded, and what evidence exists if a regulator or a court asks three years later. Those questions belong to a document layer, whether that layer is assembled from native capability, custom code, or a dedicated platform.
The Documents That Surround a Socotra Deployment
It helps to map document demand to the lifecycle rather than to a product name. For a typical property and casualty or specialty book administered on a modern core, the document estate looks something like this.
Most carriers find that a subset of these — short, transactional, highly standardised outputs closely coupled to a transaction — sit comfortably wherever they are produced today. The rest, particularly long assembled packets, jurisdictionally variable notices and correspondence that draws on data the core does not hold, are where a dedicated document layer earns its place.
Before and at bind: quotes and proposals, application and supplementary forms, subjectivity letters, binders, policy packets, declarations pages, schedules of locations or vehicles, certificates of insurance, and identification cards.
During the term: endorsement packages and change confirmations, premium-bearing and non-premium notices, mid-term cancellation and reinstatement notices, lapse and non-payment notices, invoices and instalment schedules, and ad-hoc servicing correspondence for insureds and producers.
At renewal: renewal offers and packets, premium increase notices with jurisdictional wording, non-renewal notices with statutory timing requirements, and comparison or summary documents for brokers.
In claims: acknowledgement and first-contact letters, reservation of rights letters, coverage position correspondence, settlement and release documents, payment and denial letters, and closure notices.
In compliance and finance: required notices and product disclosures, audit statements and premium audit workpapers, state or provincial filing packages, statutory and regulatory reporting extracts, tax forms, and bordereaux or data packs for reinsurers and capacity providers.
Where Document Complexity Actually Emerges
Jurisdiction, edition and effective date
A single endorsement notice can have dozens of valid variants across states, provinces and regions, each with its own required wording, notice periods and formatting conventions. The hard requirement is not simply producing the right variant today; it is reproducing the exact variant that applied on a historical effective date when someone asks for it later. That means templates and clauses need versioning and effective-dating in their own right, independent of the core’s policy versioning.
Data that is not document-ready
API-first cores return rich, nested structures: coverage arrays, exposure collections, transaction histories, nested party relationships. Documents need flattened, sorted, filtered, grouped and calculated views of that data — schedules sorted by location, limits summarised by coverage, pro-rata figures derived from transaction history. Traditionally this shaping work is written in code, which is precisely how document logic becomes a developer dependency.
Multiple systems of record
Even a well-implemented core is rarely the only source. A policy packet might need producer and commission details from an agency or distribution system, insured contact preferences from a customer relationship management (CRM) platform, loss history from a claims data store, licensed form content from a forms provider, and brand assets from a content repository. Documents are, structurally, the place where enterprise data silos collide.
Volume shape, not just volume
Document load in insurance is spiky. Renewal cycles, mass endorsements following a rate or form change, and catastrophe communications after an event all create short, intense peaks alongside steady interactive generation. Architecture that performs well at ten documents a minute may behave very differently when a renewal batch pushes tens of thousands through in an overnight window.
Failure paths
The happy path is the easy part. Serious operations design for duplicate events and idempotency, missing or null data rules, partial batch completion, delivery bounces and hard failures, retry behaviour, reconciliation between what the core thinks was sent and what actually went out, and rollback when an incorrect template version reaches production.
From core event to governed packet
An endorse event in the Socotra core triggers the document layer. Policy, CRM and distribution data converge, rules select the form edition for the effective date, the packet assembles, passes an approval gate, lands in the archive, and a document reference is written back to the core.
Socotra holds policy, billing and claims state
Native Output Versus a Centralised Document Layer
Modern core platforms, Socotra included, provide mechanisms for producing documents, and many insurers use them successfully for a portion of their output. The useful question is not which approach is superior in the abstract; it is which documents justify which treatment.
That consolidation argument strengthens when a carrier runs more than one core, which is common. Legacy books in an older system, new products on Socotra, a benefits or specialty book elsewhere: a single governed template estate spanning all of them means one set of brand standards, one approval workflow and one archive convention rather than three divergent ones.
A reasonable boundary test asks four things of each document type. Does it draw materially on data from outside the core? Does its wording vary by jurisdiction, product, brand, language or programme in ways that change frequently? Does it require review, approval or signature steps before it is final? And does it need to be reproduced exactly, years later, with full evidence of what applied?
Documents that answer "no" across the board are usually fine wherever they are produced now. Documents that answer "yes" two or more times are strong candidates for a dedicated, centralised document layer — not because the core lacks capability, but because concentrating variable, governed, multi-source content in one managed estate reduces duplication and makes change cheaper.
Integration Architecture: An API-Led Document Layer Around Socotra
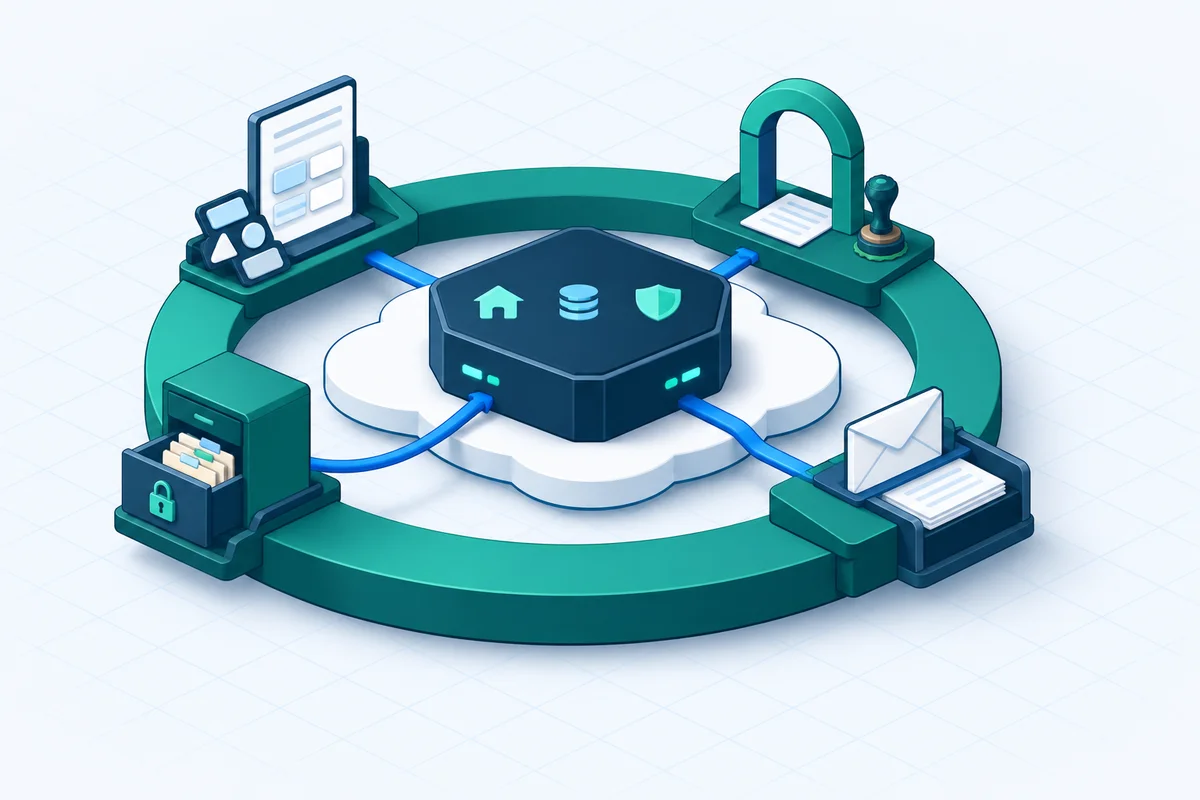
For an API-first core, an API-led document architecture is a natural fit. The pattern is straightforward and, once established, highly repeatable:
Identity and access deserve explicit design. Service identities should be scoped per integration, with permissions separated by function so that a reporting integration cannot trigger production correspondence. The Experlogix Document Automation API, for example, uses role-based API keys that define permissions at the integration level, so teams can separate responsibilities and disable an individual key without disrupting other integrations. It also exposes a documented library of actions, so generation, approval, delivery, storage and e-signature steps can be triggered over standard HTTP calls.
- Event or request. A bind, issue, endorse, invoice, renew, cancel or claim-status event — or a user action, or a scheduled batch — raises a validated trigger.
- Data retrieval under a defined contract. The document layer retrieves the policy, billing or claim data it needs, plus any supplementary data from CRM, distribution, billing or content systems. The data contract specifies required fields, types, nested structures, null handling and schema-change procedure.
- Rules and selection. Jurisdiction, product, language, brand, form edition and effective date determine which templates and clauses apply.
- Assembly. Conditional sections, filtered tables, calculations and lookups produce the finished packet.
- Approval, signature and delivery. Routing for internal approval where required, electronic signature where applicable, then delivery by email, print stream, portal or downstream system.
- Archive and write-back. The final artefact lands in the archive with metadata — template version, data snapshot reference, approver, timestamp, channel, retention rule — and a status and document reference is written back so the core and servicing teams can see it.
The practical upside of this pattern is that integration work is largely a one-time, well-bounded exercise — increasingly one that AI assistance can accelerate during mapping and configuration — after which new document types and new jurisdictional variants become configuration rather than new development. The architecture scales with volume because generation, delivery and archive steps are orchestrated services rather than bespoke code embedded in a core customisation.
Business Ownership Under IT and Compliance Control
The operational prize is not automation for its own sake. It is shifting day-to-day document change from a development queue to the teams who own the wording.
A workable ownership split looks like this. Operations and compliance own template content, clause wording, approval routing and the editorial calendar. Product owns jurisdiction, edition and effective-date decisions. IT and security own integration, identity, environments, monitoring and release controls. Nobody is asked to do another function's job, and nobody has to file a ticket to change a sentence in a renewal notice.
This is where authoring environment matters more than it first appears. Experlogix Document Automation's Template Builder uses familiar Microsoft Word functionality, so business users can build policy templates with dynamic data fields pulled from connected systems, embed jurisdiction-specific content, include dynamic tables and graphics, and rely on automatic language selection — without maintaining separate template versions by hand. Content Manager provides a structured repository for PDF forms, documents, logos, images and other assets, with linked metadata forms, field mapping and version control. Smart Forms capture data that no system currently holds, applying conditional logic and validation before that data feeds generation. Smart Flows orchestrates the steps between capture and archive, including approvals and e-signature, with each step tracked and attributed.
The honest trade-off: business ownership only works if governance is designed alongside it. Open template editing without approval gates, environment separation, change logging and release discipline trades one risk for another. The target is business-maintained content inside controls that IT, legal and compliance have specified and can audit.
AI, Governance and Agent-Initiated Document Workflows
Two distinct AI conversations tend to get conflated in insurance document programmes.
The first is AI as an implementation accelerator — assisting with mapping, suggesting template structures, drafting candidate wording for human review, and shortening the configuration cycle for new document types. The governance burden here is modest because a human approves everything before it reaches production.
The second is AI participating in live operations: an adjuster or service representative asking an internal assistant to produce a status letter, or an agent determining that an endorsement confirmation is required and initiating the workflow. This is where architecture does the heavy lifting. Experlogix offers a Smart Flows MCP server, built on the Model Context Protocol (MCP) — an emerging standard that lets AI agents connect to existing systems in a structured way. Through it, agents can discover the Smart Flows available to them, see which inputs each requires, run approved document automation workflows within existing governance, and return the resulting documents. The important design principle is that the agent invokes a pre-approved workflow rather than inventing one: approved templates, defined data sources, existing approval gates, logged actions and a traceable output.
Equally important is what AI should not do. Coverage determinations, pricing, eligibility, underwriting judgement and claim outcomes remain decisions for authorised people and systems. An AI layer that initiates a governed document workflow is a productivity gain; an AI layer that quietly makes regulated decisions is a compliance exposure. Keep the boundary explicit, keep humans in the loop at the points your regulators and your legal team care about, and keep every action logged.
Summary
Socotra gives insurers a configurable, API-first core that removes a great deal of friction from product and policy administration. The document estate around it is a separate design problem, and it rewards deliberate thinking rather than default assumptions.
The findings that matter most: decide document by document which outputs stay native and which belong in a centralised document layer, using multi-source data, variability, approval requirements and reproducibility as your test. Treat jurisdiction, form edition and effective date as first-class governance objects, not template naming conventions. Design the integration as a proper contract — events, data shape, identity, idempotency, failure handling, delivery evidence, archive metadata and write-back — because that contract is what makes future document types cheap to add. And assign ownership explicitly across operations, compliance, product and IT so that changing a notice does not require changing code.
A sensible next step is a short inventory exercise. List your document types by lifecycle stage, tag each with its data sources, variability drivers, approval requirements and retention obligations, and mark the ones that currently require a developer or consultant to change. That list, more than any vendor comparison, will tell you how much of a dedicated document layer your Socotra architecture actually needs — and which documents should be in the first wave.
Frequently Asked Questions
What role does Socotra play, and where does document production begin?
Readers who already run Socotra know the pitch: a modern core built around configurable product definitions and open APIs, so that a new product, coverage or rating change is a configuration exercise rather than a multi-quarter development project. It administers the transactional truth of the business — the policy term, the insured objects, the coverages and limits, the premium and billing position, the claim and its financials.
Where does insurance document complexity arise around Socotra?
A single endorsement notice can have dozens of valid variants across states, provinces and regions, each with its own required wording, notice periods and formatting conventions. The hard requirement is not simply producing the right variant today; it is reproducing the exact variant that applied on a historical effective date when someone asks for it later.
When is native document output enough alongside Socotra?
Modern core platforms, Socotra included, provide mechanisms for producing documents, and many insurers use them successfully for a portion of their output. The useful question is not which approach is superior in the abstract; it is which documents justify which treatment. That consolidation argument strengthens when a carrier runs more than one core, which is common.
How should a governed document layer connect with Socotra?
For an API-first core, an API-led document architecture is a natural fit. The pattern is straightforward and, once established, highly repeatable: Identity and access deserve explicit design. Service identities should be scoped per integration, with permissions separated by function so that a reporting integration cannot trigger production correspondence.
Who should own document templates, approvals and governed changes?
The operational prize is not automation for its own sake. It is shifting day-to-day document change from a development queue to the teams who own the wording. A workable ownership split looks like this. Operations and compliance own template content, clause wording, approval routing and the editorial calendar.