ReferenceConnect is Vertafore’s online insurance reference library — the place underwriters, account managers and claims staff go to look up coverage interpretations, forms commentary, rules guidance and legal analysis from licensed publishers rather than guessing from memory. It sits beside, not inside, the systems that actually issue policies and pay claims, which is where the friction starts: research answers a question, but someone still has to turn that answer into approved wording inside a declaration, an endorsement, a coverage position letter or a renewal packet. When that translation happens by copy-and-paste, the organisation inherits version drift, licensing exposure and an audit trail that stops at someone’s desktop. Done well, the same journey — research, approved clause, governed template, generated document, retained evidence — becomes a controlled production line rather than a scramble.
TL;DR
- ReferenceConnect is a research and reference resource, not a policy administration system, rating engine or document generator. Its value in a document strategy is upstream: it informs what the wording should say, not what the system automatically prints.
- The gap most insurers and agencies underestimate is the hand-off between licensed research, internally approved clause language, production templates and the final generated document. Each of those is a distinct artefact with a distinct owner.
- Copy-and-paste from reference material into customer documents creates three compounding problems: licensing ambiguity, no version control, and no provable link between the wording used and the research that justified it.
- A governed document layer — templates, clause libraries, rules, approvals, delivery and archive — gives that chain a home. Experlogix Document Automation is one way organisations centralise it across a core policy system, an agency management system and other back-office sources.
- The practical goal is modest and valuable: the business owns wording and logic, IT owns integration, identity and release control, and every document can be traced back to the clause version, data and approver behind it.
Happy shiny people. The industry’s advertising loves to show policyholders living their best lives, blissfully unbothered by the catastrophes their cover protects against; a centralised document layer that lets the business own templates and workflows accurately and quickly, without heavy ongoing IT labour, lets the insurance professionals behind those policies live their best lives too.
What ReferenceConnect Actually Does — and What It Deliberately Does Not
Precision matters here, because ReferenceConnect is frequently grouped with core insurance platforms when people describe their technology estate. It belongs to a different layer. ReferenceConnect aggregates licensed insurance reference and research content — coverage analysis, forms and rules commentary, legal and regulatory material, and publisher libraries — into a searchable resource that insurance professionals consult while making judgements.
That means ReferenceConnect is a source of understanding, not a system of record and not a document production engine. It does not hold your policy state, your claim state, your billing schedule or your producer records. It does not assemble a policy packet. It does not know which jurisdiction-specific notice your renewal requires next month.
Framing it accurately changes the document conversation in a useful way. The question is not “how do we get ReferenceConnect to generate documents?” It is: how does what we learn in ReferenceConnect become approved, versioned, effective-dated wording that our document generation and document workflows can reliably reproduce?
The four artefacts people conflate
- Licensed reference material. Publisher content accessed under subscription terms. Research and interpretation — not drop-in production text.
- Internally approved clause language. Wording your legal, compliance and product teams have authorised for customer-facing use, with an owner, a version and an effective date.
- The template. The assembled document design — declarations, schedules, conditional sections, tables, branding — that pulls live data and selects the right clauses.
- The generated document. The artefact delivered to a policyholder, broker, regulator or reinsurer, plus the evidence of what produced it.
Treating these as one thing is what produces the familiar failure: a claims letter quoting commentary that was never approved for external use, or an endorsement built on last year’s interpretation because nobody tracked which clause version had changed.
Where the Document Work Really Happens Around Research
ReferenceConnect gets consulted at the moments where documents are most consequential. Mapping those moments is the fastest route to a sensible document automation plan.
- New business and submission. Underwriters research coverage forms, exclusions and endorsement interactions before quoting. The outputs are quote letters, proposals, binders and submission packets — documents that must reflect the coverage decision precisely.
- Policy issuance. Declarations, master policies, evidence of coverage, certificates and policy packets assemble dozens of selected forms. Research informs which forms apply; the document layer must reproduce the correct edition of each, every time.
- Endorsements and mid-term changes. A coverage question is researched, a change is agreed, and the endorsement must carry the right language with the right effective date — including when the document is reproduced two years later during a dispute.
- Renewals. Renewal packages, premium increase notices and revised schedules are where changed forms, changed rules and changed jurisdiction requirements quietly accumulate. Research identifies the change; template governance has to land it everywhere it applies.
- Claims. Coverage position letters, reservation of rights correspondence, denials and status updates are the most research-sensitive documents an insurer produces. They demand approved wording, review workflow and a durable record of what was sent, to whom and when.
- Audits, compliance and regulatory work. Required notices, product disclosures, audit reports and state, provincial or regional filing packages all depend on current rules — and all need to be demonstrably correct after the fact.
- Agent and broker communications. Where ReferenceConnect sits in a Vertafore-centred environment alongside an agency management system, the same interpretations drive certificates, proposals, summaries of insurance and servicing correspondence.
Why Document Complexity Outgrows Manual Methods
Insurance documents are difficult for structural reasons, not because teams are careless.
Jurisdictional variation. Wording varies by state, province and region, and often by product and distribution channel within the same book. One national mailing can require dozens of conditional variants.
Effective dating and form editions. Insurance is retrospective. Reproducing a document as it stood on a given date — the right form edition, the right clause version, the right disclosure set — is a basic regulatory expectation and a surprisingly common gap.
Dynamic clauses and conditional logic. Which exclusions appear, which schedules expand, which notices attach — these depend on rules that traditionally live in developer-maintained code or consultant-maintained scripts, making every wording change a project.
Multi-source data. A single policy packet may need policy data from the core system, client and producer data from the agency management system, billing data from the finance platform, and location or exposure schedules from a spreadsheet or data warehouse. That data rarely arrives in a shape you can print as-is; it needs unpacking, filtering, calculation and look-up before it becomes a readable table.
Volume peaks. Renewal cycles, mass endorsements following a rule change, and catastrophe communications all arrive as bursts, not steady flow. Long commercial schedules compound the load.
Research tools sharpen the judgement behind these documents. They do not resolve the production mechanics, and no reference library claims to.
From research to governed wording
How a Governed Document Layer Closes the Gap
The architectural idea is straightforward: keep each system doing what it is best at, and give the document chain a single governed home.
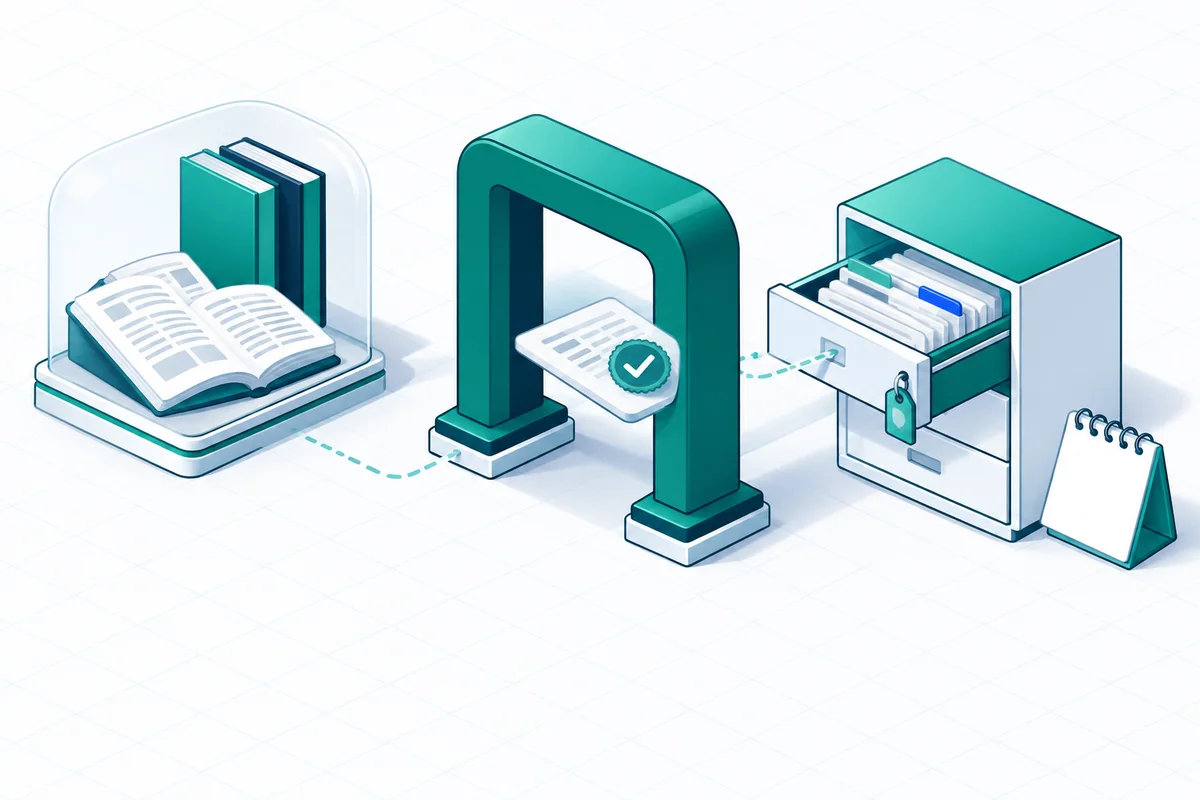
Experlogix Document Automation is commonly deployed in that role alongside existing insurance technology rather than in place of it. The core platform remains authoritative for policy, billing and claim state. The agency management system remains authoritative for client, producer and servicing context. ReferenceConnect remains the research authority. The document layer owns templates, clause content, assembly rules, workflow routing, delivery and the evidence trail.
Several Experlogix capabilities map directly onto the problems above. Templates are built in a low-code Template Builder that uses familiar Microsoft Word functionality, so business users can create and maintain sophisticated designs — dynamic data fields, jurisdiction-specific content, dynamic tables and graphics, automatic language selection — without coding. Embedded business rules apply jurisdiction-specific language and disclosures automatically, which removes the need to maintain separate template versions by hand. Edits, approvals and timestamps are logged through audit trails, producing a regulator-ready record, while metadata tagging and automated archiving support quick retrieval during an audit. Smart Forms collect data that does not already exist in a CRM or core system, so a workflow can send a form link, and form completion can trigger document generation.
The practical consequence for a research-driven workflow is this: approved wording can be maintained once, in a controlled clause and template estate, and reused across every document type and every connected system — rather than re-keyed into each core platform's native output separately.
Keeping licensed content on the right side of the line
A discipline worth stating plainly: reference material accessed through ReferenceConnect is licensed research. It should inform an internal approval process, not flow automatically into customer-facing output. A workable pattern is a deliberate gate — research informs a drafting proposal, legal and compliance approve the resulting internal clause, the approved clause is published to the governed clause library with an owner, version and effective date, and only then is it available to templates. The audit question "why does this sentence say what it says?" then has an answer that lives in your governance records, not in someone's browser history.
Integration Architecture, Stated Simply
Most of this comes down to triggers and data contracts.
API-led integration is the backbone. An event in the core system or agency platform — bound, endorsed, renewed, claim status changed — calls the document service with a defined payload; the document layer retrieves any additional data it needs, selects templates and clauses by jurisdiction, product, brand, language and effective date, assembles the output, routes it for approval or signature, delivers it, archives it, and writes status and document references back to the originating system.
The Experlogix Document Automation API is designed for exactly this kind of embedding, with role-based API keys and an extensive library of API calls so IT can integrate document generation into virtually any application, and it can connect to an unlimited number of data sources. Out-of-the-box integrations exist for major business platforms including Microsoft Dynamics 365 and Salesforce. Security posture matters to this conversation too: Experlogix maintains SOC 2 compliance and follows industry standards including NIST and OWASP guidance.
This is a one-time integration design, increasingly assisted by AI during configuration, that then carries ongoing volume: interactive one-off generation during a servicing call, queued generation at bind, and scheduled batch generation for renewal cycles and mass notices. Framed as a business enabler, it means wording changes stop being release-dependent — IT owns the pipe, operations owns the content flowing through it.
The failure paths worth designing before go-live
- Missing or null data rules — suppress, substitute, or halt and raise an exception?
- Idempotency, so a duplicated event does not send a policyholder two cancellation notices.
- Retry and reconciliation for failed generation, failed delivery and failed write-back.
- Partial batch handling, so a 20,000-document renewal run that fails at 14,000 can resume without duplicates.
- Monitoring and alerting with named operational owners, not just technical logging.
- Peak-volume testing against realistic worst cases: renewal season plus a catastrophe event plus long commercial schedules.
Business Ownership, AI and Honest Trade-Offs
The ownership model is the point. Operations and compliance maintain wording, clause versions and approval routing. Product decides jurisdiction, edition and effective-date logic. IT and security own integration, identity, environments, monitoring and release control. That division is what reduces dependency on developers and specialist consultants for routine wording changes — not a claim that IT disappears, but a claim that IT's involvement shifts from every template edit to the architecture that supports them.
AI belongs in this picture as assistance and orchestration under governance, not as a decision-maker. Experlogix Document Automation includes an MCP (Model Context Protocol) server, which allows AI agents to connect to existing systems in a structured, auditable way — so an agent can act on context from a policy management platform, CRM or compliance engine within parameters the organisation defines. Every document generated through Experlogix is traceable and every agent action is logged, with humans retaining control over where the boundaries sit. The appropriate use cases are productivity ones: a service representative asking an internal assistant to start a correctly governed endorsement packet, AI-assisted template drafting, AI-assisted workflow configuration, and review support that flags inconsistencies for a human to resolve. Coverage, pricing, eligibility, underwriting and claims decisions remain with authorised people and systems.
The trade-offs deserve naming. Introducing a document layer adds an integration to design, test and support. It requires genuine governance — a clause owner, an approval path, a retention policy — rather than an implied one. Some documents are better left native to the core platform, particularly tightly coupled transactional output with no cross-system data needs. And a centralised template estate only pays off if the organisation actually consolidates onto it; running it as a fourth silo alongside three existing ones helps nobody. This is one defensible architectural approach, not the only one.
Summary
ReferenceConnect earns its place as a research and interpretation resource, and it should be evaluated on that basis rather than as a document production tool. The opportunity for insurers and agencies is in the chain that follows the research: approved clause language, governed templates, multi-source document generation, controlled document workflows, delivery, archive and evidence.
Three decisions carry most of the weight. First, draw explicit boundaries between licensed reference content, internally approved wording, templates and generated artefacts, and name an owner for each. Second, decide deliberately which documents stay native to your core or agency platform and which justify a centralised document layer that can draw from several systems at once. Third, design the unglamorous parts — missing data, duplicate triggers, retries, partial batches, reconciliation, monitoring and retention — before the first production run rather than after the first incident.
A reasonable next step is to pick one research-sensitive document type — claims coverage position letters or jurisdiction-specific renewal notices are good candidates — and trace it end to end: where the wording came from, who approved it, which version applied on the effective date, what data populated it, how it was delivered, and what evidence exists today. Whatever that exercise reveals will tell you far more about your document automation priorities than any platform comparison, and it gives operations, compliance and IT a shared, concrete map to work from.
Frequently Asked Questions
What role does ReferenceConnect play, and where does document production begin?
Precision matters here, because ReferenceConnect is frequently grouped with core insurance platforms when people describe their technology estate. It belongs to a different layer. ReferenceConnect aggregates licensed insurance reference and research content — coverage analysis, forms and rules commentary, legal and regulatory material, and publisher libraries — into a searchable resource that insurance professionals consult while making judgements.
Where does document production begin after using ReferenceConnect research?
ReferenceConnect gets consulted at the moments where documents are most consequential. Mapping those moments is the fastest route to a sensible document automation plan . New business and submission. Underwriters research coverage forms, exclusions and endorsement interactions before quoting. The outputs are quote letters, proposals, binders and submission packets — documents that must reflect the coverage decision precisely.
Where does insurance document complexity arise around ReferenceConnect?
Insurance documents are difficult for structural reasons, not because teams are careless. Jurisdictional variation. Wording varies by state, province and region, and often by product and distribution channel within the same book. One national mailing can require dozens of conditional variants. Effective dating and form editions.
How can Experlogix Document Automation complement ReferenceConnect?
The architectural idea is straightforward: keep each system doing what it is best at, and give the document chain a single governed home. Experlogix Document Automation is commonly deployed in that role alongside existing insurance technology rather than in place of it.
How should a governed document layer connect with ReferenceConnect?
API-led integration is the backbone. An event in the core system or agency platform — bound, endorsed, renewed, claim status changed — calls the document service with a defined payload; the document layer retrieves any additional data it needs, selects templates and clauses by jurisdiction, product, brand, language and effective date, assembles the output, routes it for approval or signature, delivers it, archives it, and writes status and document references back to the originating system.