NCCI, the National Council on Compensation Insurance, sits quietly behind an enormous amount of workers compensation paperwork. It is a licensed rating and statistical organisation that develops workers compensation classifications, manual rules, loss costs, experience rating values, and the standard forms and endorsements that carriers adopt in the states where it operates. The practical challenge for carriers and programme administrators is not understanding NCCI content. It is getting that content into issued policy packets, endorsement notices, audit letters, and producer communications quickly and consistently, with the correct edition, jurisdiction, and effective date, and without a developer release for every circular. Left unsolved, this becomes a slow, IT-dependent bottleneck that delays filings, creates version drift across books of business, and makes audits harder than they need to be.
TL;DR
- NCCI is the source of authoritative workers compensation classifications, manual rules, forms, endorsements, and experience rating values in the states it serves. It is not a policy administration system, a document generator, or an archive.
- The operational difficulty is the translation layer: moving licensed, effective-dated NCCI content into approved production wording, assembled packets, and reportable transactions across multiple core systems.
- The documents that carry the most risk depend on data from several systems at once. These include declarations, schedules of endorsements, experience modification notices, audit correspondence, and cancellation and non-renewal notices.
- A governed document layer, such as Experlogix Document Automation, can sit alongside the core platform to handle template governance, multi-source assembly, approvals, delivery, and audit evidence, while the core remains the system of record.
- Business ownership is the point. Operations and compliance maintain wording and logic in familiar tools, and IT retains control of integration, identity, environments, and releases.
Happy shiny people. Insurance marketing loves the image of policyholders living their best lives, blissfully unbothered by the risks their cover absorbs. A centralised document layer that lets business teams manage document automation accurately and quickly, without heavy ongoing IT labour, extends the same courtesy to the insurance professionals who actually produce the documents.
What NCCI Actually Owns, and What It Does Not
NCCI’s role in workers compensation is advisory, statistical, and regulatory-facing. It maintains the classification system used to describe exposure, publishes manual rules and interpretations, files loss costs and rating values with regulators in participating states, administers experience rating, and collects policy and unit statistical data from carriers. It also publishes the standard workers compensation policy forms and the long tail of endorsements that tailor those forms by state, coverage, and circumstance.
What NCCI does not do is run your business. It does not issue your policies, assemble your packets, apply your brand, manage your approval chain, deliver your notices, or store the evidence that a particular insured received a particular document on a particular date. Those responsibilities sit with the carrier, its policy administration system, and whatever document generation and document workflow capability surrounds it.
Several jurisdictions make this picture more interesting. Independent rating bureaux operate in some states, monopolistic state funds operate in others, and large national or multi-state programmes often write business across a mix of all three. Carriers writing beyond the United States face the same pattern with provinces and regions governed by their own authorities. As a result, a single workers compensation book may need several content lineages maintained at the same time, and every one of them has an effective date.
Where Document Complexity Emerges in Workers Compensation
Workers compensation is unusually document-dense, and the complexity is rarely in any single document. It is in the combinations.
New business and policy issuance. A workers compensation packet typically brings together the information page, the standard policy forms, state-specific endorsements selected by rule, schedules of locations and classifications, and any programme-specific wording. Each selection depends on jurisdiction, class code, coverage election, and effective date.
Endorsements. Mid-term changes, such as adding a state, adding a location, changing an officer exclusion, or correcting a classification, generate their own documents and often a revised schedule. Mass endorsement events following a rule or loss cost change can hit thousands of policies at once.
Experience rating. Experience modification factors arrive, change, and sometimes get revised retroactively. Each change can require a notice, a revised information page, and a premium adjustment explanation that the insured and the agent can actually follow.
Premium audit. Audit scheduling letters, records requests, audit results, disputed-audit correspondence, and revised billing documents form a sequence where tone, timing, and regulatory wording all matter.
Billing, cancellation, and non-renewal. Notice content, timing, and proof of delivery are governed by state requirements, and the evidence trail matters more than the document’s appearance.
Reporting and compliance. Because of policy and unit statistical reporting obligations, document production and data reporting draw on overlapping facts. Discrepancies between what was issued and what was reported create rework later.
Producer and employer communications. Certificates, renewal proposals, loss run summaries, and safety or return-to-work materials round out the picture.
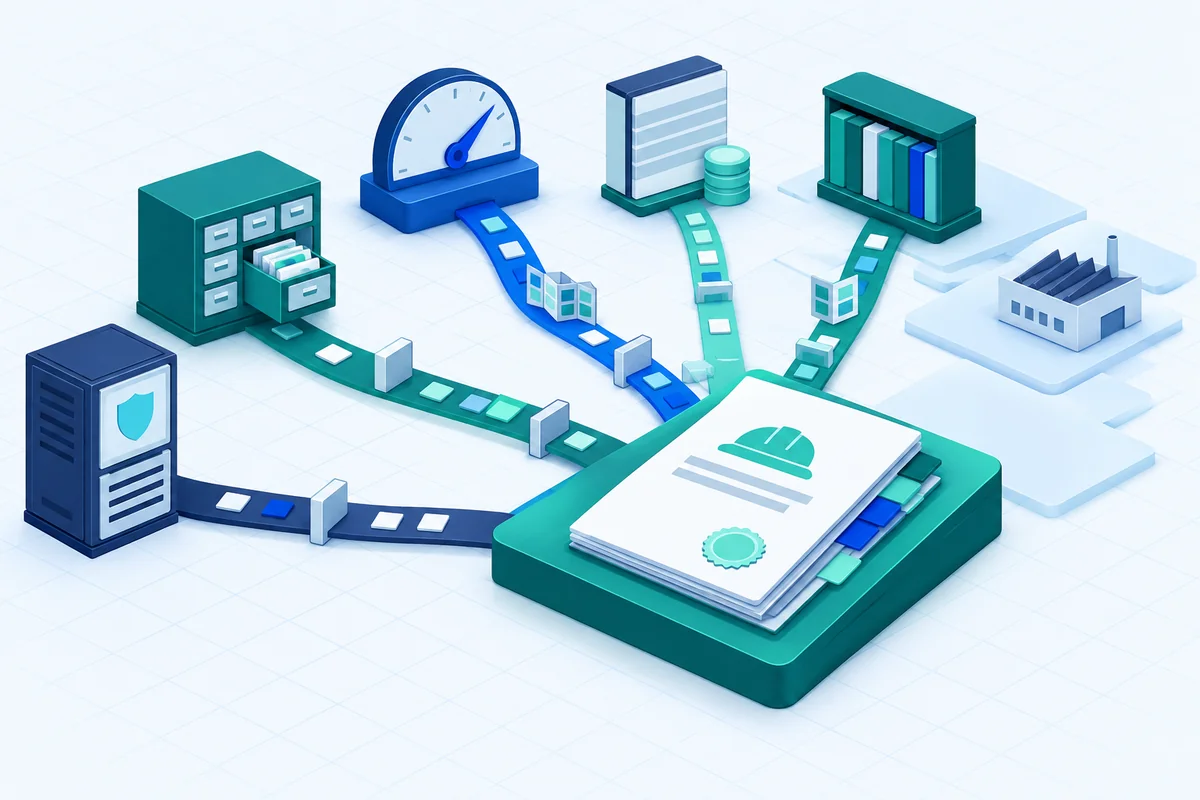
Underneath all of it is a data problem. The declarations need:
- policy data from the core system
- exposure and classification data from rating
- experience values from the rating organisation’s output
- billing figures from the billing system
- brand and wording from a content library
Very little of that source data goes straight into a document as-is. It needs filtering, calculations, look-ups, and the unpacking of nested structures such as multi-state, multi-location schedules. Historically, that work has meant code, and code means developers, consultants, and release cycles.
From Licensed Content to Approved Production Wording
Many document automation programmes stumble on one distinction: licensed advisory content, research material, and commentary are not the same thing as approved production wording.
NCCI materials are licensed, and their use is governed by the terms a carrier has agreed to. Research tools and manuals inform the decision about which form edition applies and how a rule should be interpreted. They do not automatically become the text of an issued document. A disciplined content chain looks like this:
- Source material: licensed manuals, rules, circulars, and form editions, used within licence terms.
- Interpretation: product, compliance, and legal teams decide what applies, where, and from when.
- Approved content: reusable clauses, notices, and form representations, versioned and signed off.
- Template logic: rules that select content by jurisdiction, product, class, coverage, and effective date.
- Generated output: the issued document, with its own retained record of exactly what was used.
Keeping these layers separate lets a carrier answer the questions regulators and auditors eventually ask:
- Which edition of which form was used?
- Which rule selected it?
- Which data went into it?
- Who approved it?
- How was it delivered?
- Where is it retained?
Which Documents Stay Native, and Which Justify a Dedicated Document Layer
Most modern policy administration platforms include some form of document production, and many workers compensation carriers use it well for the high-volume, highly standardised core of the book. The realistic question is not whether native output works. It is where native output stops being the most efficient place to do the work.
The boundary usually falls along these lines:
Good candidates to stay native: transaction-bound documents that depend only on core data, change rarely, and need no external orchestration.
Strong candidates for a dedicated document layer: documents that pull from several systems at once, carry heavy conditional wording, need fast maintenance by business users, require approval routing or signatures, or must be reproduced years later exactly as issued.
This is an architectural option, not a verdict. Plenty of carriers run both. The useful exercise is to map ownership explicitly:
- Which system owns the source data?
- Which system owns the trigger?
- Which system owns the template?
- Who approves wording?
- Who holds delivery evidence?
- Which system archives the final document?
- What gets written back to the core?
How Experlogix Document Automation Fits Around NCCI-Driven Workflows
Experlogix Document Automation is designed to sit alongside existing insurance systems rather than replace them. It acts as a governed layer for document generation, document workflows, delivery, and evidence.
Several components map directly onto workers compensation realities:
- Template Builder is a Microsoft Word add-in. Operations and compliance staff design templates in a familiar environment using dynamic data fields, conditional content, data-driven tables, embedded digital content, and version control, with multi-language support where it is needed.
- Content Manager is a secure, structured repository for digital assets such as PDF forms, documents, logos, images, and multimedia. Content is organised in a familiar folder structure, with metadata, field mapping, search, and version control.
- Smart Forms capture structured data where a system of record does not already hold it, using validation and conditional logic, and feed it directly into document workflows.
- Smart Flows provides low-code, drag-and-drop workflow automation to create, generate, manage, store, deliver, and e-sign documents. It integrates with Microsoft Power Automate for broader orchestration.
For a workers compensation carrier, that translates into practical patterns:
- One governed set of templates can serve several cores and programmes.
- Jurisdiction-specific content can be embedded in templates, with automatic language selection, so separate template versions do not have to be maintained by hand.
- Revised wording can be routed for approval.
- Audit trails log edits, approvals, and timestamps, creating a regulator-ready record.
Integration as a Business Enabler
Connectivity is handled through the Experlogix Document Automation API, which offers an extensive library of API calls and role-based API keys. Role-based keys matter when documents must only be generated by authorised services and roles.
Integration is a one-time design exercise that keeps paying off. Once the core platform and the document layer agree on what data passes between them, new templates, jurisdictions, and document types can use the same interface without new development each time. The same architecture also handles scale, whether the job is a single interactive declarations page or a renewal batch running into the tens of thousands.
Some behaviours are worth designing deliberately rather than discovering in production:
- What happens when expected data is missing.
- Idempotency, so a duplicated trigger does not issue a duplicate notice.
- Retry and reconciliation for partial batches.
- Handling of delivery failures.
- Monitoring that tells operations which documents did not complete.
Governed AI, Not Autonomous Decisions
AI belongs in this picture as an assistant that speeds up work within defined boundaries. Experlogix's Smart Flows MCP (Model Context Protocol) server allows AI agents to run document automation workflows securely, with governance applied and results returned. In other words, an agent starts a governed workflow rather than improvising a document. Every document generated through Experlogix is traceable and every agent action is logged, which is the condition under which AI is usable in a regulated line at all.
In workers compensation, the boundary should be explicit. Classification decisions, experience rating application, coverage determinations, and claim outcomes stay with authorised people and authorised systems. AI helps with configuration, content suggestions, review, and faster workflows. That help is supervised, auditable, and bounded by business rules.
Business Ownership and the Speed of Regulatory Change
The recurring frustration in workers compensation document operations is the delay between a rule or form change and the moment issued documents reflect it. When wording lives in code, that delay is a development queue. When wording lives in a governed template and content library maintained by the business, the queue shortens considerably. Compliance oversight also improves rather than weakens, because changes are versioned, approved, and logged rather than buried in a release.
The sensible division of labour is straightforward. IT establishes integration, identity, environments, security, and release controls. Operations and compliance own templates, clauses, approvals, and the effective dates that govern them. IT sets it up once, and the business runs it from then on.
Summary
NCCI provides the authoritative workers compensation content that carriers must apply accurately across every state where they write: classifications, manual rules, forms, endorsements, and rating values. The documents themselves, and the workflows around them, remain the carrier's responsibility. That is where most of the operational cost and compliance exposure sits.
Three considerations are worth carrying into any evaluation:
- Keep the layers separate. Treat licensed source material, approved wording, template logic, and generated output as distinct governed layers. Preserve form edition and effective date so historical documents can be reproduced faithfully.
- Map ownership first. Decide who owns data, triggers, templates, approvals, delivery evidence, archive, and write-back before choosing what stays native and what moves to a dedicated document layer.
- Design for failure. Treat missing data, duplicate triggers, partial batches, and delivery failures as core design work rather than an afterthought.
A reasonable next step is to pick one high-friction workflow, such as mass endorsements following a rule change or the premium audit correspondence sequence, and trace it end to end. Note what data it needs, which systems hold it, who approves the wording, how long a change currently takes, and who has to be involved. That single map usually shows where a governed document layer earns its place, and where your existing platform is already doing the job well.
Frequently Asked Questions
What role does NCCI play, and where does document production begin?
NCCI's role in workers compensation is advisory, statistical, and regulatory-facing. It maintains the classification system used to describe exposure, publishes manual rules and interpretations, files loss costs and rating values with regulators in participating states, administers experience rating, and collects policy and unit statistical data from carriers.
Where does insurance document complexity arise around NCCI?
Workers compensation is unusually document-dense, and the complexity is rarely in any single document. It is in the combinations. New business and policy issuance. A workers compensation packet typically brings together the information page, the standard policy forms, state-specific endorsements selected by rule, schedules of locations and classifications, and any programme-specific wording.
How should licensed insurance content be handled before document production?
Many document automation programmes stumble on one distinction: licensed advisory content, research material, and commentary are not the same thing as approved production wording. NCCI materials are licensed, and their use is governed by the terms a carrier has agreed to. Research tools and manuals inform the decision about which form edition applies and how a rule should be interpreted.
When is native document output enough alongside NCCI?
Most modern policy administration platforms include some form of document production, and many workers compensation carriers use it well for the high-volume, highly standardised core of the book. The realistic question is not whether native output works. It is where native output stops being the most efficient place to do the work.
Who should own document templates, approvals and governed changes?
The recurring frustration in workers compensation document operations is the delay between a rule or form change and the moment issued documents reflect it. When wording lives in code, that delay is a development queue. When wording lives in a governed template and content library maintained by the business, the queue shortens considerably.